 insomnius

This is not an S3 problem. It shows up most often as "my upload endpoint is OOM-ing", but the underlying mistake — making the control plane do data-plane work — is the same shape behind email attachments, database BLOBs, log shipping, and webhook payloads. Once you see it once, you see it everywhere.
A user uploads an 8 GB video. Your API server's memory hits 80 %. Unrelated requests time out. The pod gets OOM-killed. You scale up the replicas. Two more users start uploading. Three pods fall over.
Nothing in your code looks wrong. The handler is straightforward:
app.post("/upload", async (req, res) => {
  const file = req.body         // multipart parser buffers the whole thing
  await s3.putObject({           // then we stream it forward to the bucket
    Bucket: "uploads",
    Key: file.name,
    Body: file.buffer,
  })
  res.status(201).end()
})
That handler is doing one thing wrong, but it's a structural thing. Your app server — the place that authenticates users, looks up rows, publishes events, computes prices — has been quietly drafted into a second job: proxying gigabytes of binary data. Every byte of that 8 GB enters your pod, sits in memory or a temp file, and exits to the bucket. You're paying RAM, CPU cycles, doubled bandwidth, and request-queue depth for work that has nothing to do with your business logic.
Watch the bytes flow
Four patterns, one client, one bucket. Toggle below to see what each does to the app server in the middle — and notice the gap between the last two: chunking and parallelism are independent wins, and only one of them moves the throughput needle.
One big file. Client streams the whole body to your API; the API buffers it and forwards to the bucket. Every byte traverses the app server twice.
In Through app, the entire 8 GB body goes Client → App → Bucket as one stream. The app's memory bar climbs as bytes accumulate (in real systems, this is buffer pools, multipart parsers, or a temp file holding the body until upstream is ready). In Presigned URL, the client gets a time-limited PUT URL from the app and PUTs the same monolithic body straight to the bucket — bytes pass right through where the app would otherwise have intercepted them. In Multipart sequential, the app returns an array of N signed URLs (one per part); the client splits its local blob into N pieces to match the array length and uploads them directly to the bucket one at a time: same per-byte cost as a single PUT, plus per-part handshake overhead — what you've actually bought is resumability, not speed. In Multipart parallel, the flow is identical — N URLs in, N pieces out — but the parts upload concurrently to the bucket using their per-part URLs; that's where the throughput improvement actually lives.
All three direct modes start with a small control-plane round-trip — visible in the animation as the unfilled ? / URL pill bouncing client → app → client before any bytes move. The client is asking the app for a signed credential; the app signs it (one URL for single-PUT modes, an array of URLs for multipart) and sends it back. The number of URLs the app returns is the number of parts — the client doesn't pick the part count; it slices its local blob to match what the app issued. Only after that handshake does the client open data-plane connections to the bucket. The handshake is a few hundred bytes of JSON, so it's cheap — but it's the reason the app still has a job: it's the credential issuer and shape decider, not the byte forwarder.
Why through-app is the wrong shape
The cost has three parts and they all bite at the same time.
- Memory pressure. Even with streaming parsers, multipart-form parsing on most frameworks buffers a part header, sometimes the whole part. A 5 GB upload with
multerdefaults will sit in/tmpuntil S3 acks it. With 50 concurrent uploads of 1 GB each, you've signed up for 50 GB of disk-or-RAM that wasn't in your capacity plan. - Doubled bandwidth. Bytes leave the client into your VPC, then leave your VPC again into the bucket's API endpoint. You pay egress / cross-AZ for the second hop and the bandwidth meter on your VPS shows 2× the upload size.
- Tail latency on unrelated work. Your
/uploadhandler holds an HTTP connection open for as long as the slowest client takes to send. Connections held = workers blocked = queue depth growing for everything else the app does. The user trying to log in pays for the user trying to upload.
The framing fix is simple: a bucket already speaks HTTPS, already authenticates uploads with signed URLs, already supports parallel multipart uploads, and already scales horizontally. Your app server doesn't need to relay bytes; it needs to grant permission to the bucket and stay out of the way.
Same shape, different surface
Anywhere your application code is asked to be a courier for data it doesn't need to inspect, the same anti-pattern is hiding. A short tour:
- DB BLOB columns. Storing 200 MB videos as
BYTEAorLONGBLOBrows. The DB now backs up tens of TB of data it can't index. Postgres dumps take an extra hour. Replication lag spikes whenever someone uploads a marketing reel. The fix is the same: store the bytes in object storage; keep a URL string in the row. - Email attachments. Embedding a 12 MB PDF in an SMTP message instead of linking. Your transactional email gets rejected by recipient servers' size limits. Mail queues back up. The fix: upload to a bucket, email a presigned download URL.
- Webhook payloads with bodies. Sending the contents of a generated report in the webhook body. The recipient now has to handle 50 MB POSTs from you. The fix: webhook with a URL pointing at the report; recipient downloads only if they care.
- Log shipping through the app. Forwarding application logs through your gateway to a log store. The gateway becomes a memory hog. The fix: log straight to S3 / Loki / ClickHouse from the source process; the gateway only queries.
- CDN passthrough. Serving images from your origin instead of letting the CDN cache them at the edge. Origin saturates on viral content. The fix is the inverse of upload-direct: download direct from cached storage.
- Database export endpoints. A "download CSV" endpoint that streams a 4 GB query result through the API process. Memory climbs, the connection holds, and your API egress is now coupled to your analytics workload. The fix: kick off an async export to a bucket, email a download link when ready.
The substrate changes — Postgres, SMTP, webhooks, syslog, the CDN — and the verb changes — attach, embed, forward, proxy, cache. The diagnosis doesn't: a layer that should be coordinating is being asked to carry. Move the bytes through the dedicated path; keep the control-plane path on coordination work.
Three ways to fix it
1. Presigned URL (single PUT)
Server signs a short-lived URL granting PUT access to a single object key. Client uploads with one HTTPS request. Use this when the file is small enough that a single retry on failure is acceptable (rule of thumb: < 100 MB for typical browser uploads).
1. Client → App: "I want to upload `report.pdf`"
2. App → Client: "Here's a signed PUT URL, valid for 15 minutes"
3. Client → Bucket: PUT directly with the URL
Throughput is one connection's worth, but the app is fully out of the byte path.
2. Multipart upload + presigned per part
For files large enough that you need parallelism or resume-on-failure (anything past a few hundred MB):
1. Client → App: "I want to upload an 8 GB video"
2. App → Bucket: CreateMultipartUpload → uploadId
3. App: decides part count N (file size, S3's 5 MiB minimum, 10,000-part cap)
4. App → Client: { uploadId, [signed URL for part 1, ..., signed URL for part N] }
5. Client: slices local blob into N pieces to match the array length
6. Client → Bucket: PUT each part in parallel using its signed URL
7. Client → App: "I'm done; here are the part ETags"
8. App → Bucket: CompleteMultipartUpload(uploadId, [{partNumber, eTag}, ...])
Note who decides what. Part count is a control-plane decision the app makes — it knows the file size from step 1, knows the S3 constraints (parts must be >= 5 MiB except the last, max 10,000 parts per upload), and may also factor in per-partition rate limits or its own retry granularity. The client's job is purely data plane: take the array of URLs, slice its local blob into exactly that many pieces, and PUT each piece to its corresponding URL. The shape of the upload comes from the server; the bytes come from the client.
Parts can be uploaded in any order, in parallel, and individually retried. The app sees three short JSON requests; the bucket sees the entire data plane. The parallelism is the throughput win — uploading the parts serially (as the third toggle in the visualization shows) buys you resumability but not speed; you've added per-part handshake overhead without taking advantage of the bucket's concurrent-write headroom.
A practical ceiling worth knowing: browsers cap concurrent connections at six per origin under HTTP/1.1. Sign 50 part URLs and only six parts will actually be in flight at once — the rest queue in the browser's connection pool. For most uploads this is fine (six parallel streams to S3 already saturates a typical home or office uplink), but it's why doubling part count past a certain point stops helping wall-clock time. If you need to break the cap, point your client at an HTTP/2-capable bucket endpoint (S3 supports it on most regions; check before relying on it) and a single multiplexed connection will carry all parts concurrently. From a server uploader (no browser cap), use a tuned thread or async pool — typically 8–32 parallel parts is the sweet spot before you start fighting AWS request-rate limits per partition.
3. Resumable / chunked uploads (GCS, tus.io, S3 with manifest)
Some clients (mobile uploaders, flaky networks) need a resume token they can re-use after an interrupted upload. Google Cloud Storage's resumable uploads and the tus.io protocol are the well-trodden options. The shape is identical: app issues a credential or session, client streams to storage, app finalizes. The only addition is a "where did we leave off?" exchange.
Three signals you have one
- App pod memory or
/tmpsize correlates with upload traffic, not request count. A login spike doesn't move it; an upload spike does. - App egress bytes ≈ 2× client ingress bytes. Every byte enters and leaves; you're paying twice on the same data.
- Latency on unrelated endpoints worsens during big uploads. Your
/healthzshouldn't care about a marketing video, but if it does, your workers are tied up in upload handlers.
Rule of Thumb
Your app server is for orchestration: auth, business logic, deciding whether and where something can happen. Object storage is for bytes. When you find your app code in the byte path — copying buffers, decoding multipart, calling s3.putObject(body=blob) — you've crossed the line. Move the data plane to where it belongs and reduce your app's job to issuing tickets.
The pattern generalizes beyond uploads. Anywhere a control-plane component is being asked to carry payloads — emails, webhooks, exports, BLOB columns, log forwarders — ask whether the carrier needs to see the bytes at all. Most of the time, the answer is no, and the fix is to issue a credential and step out of the way.
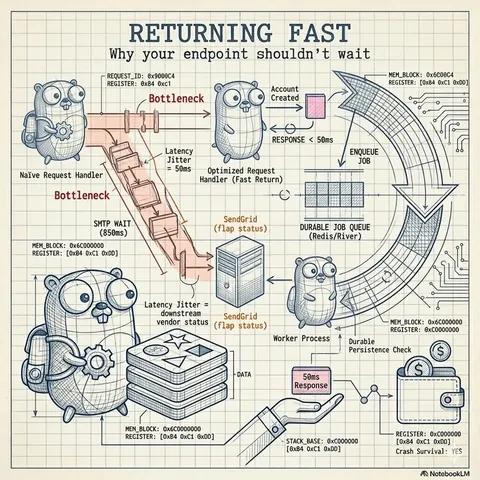
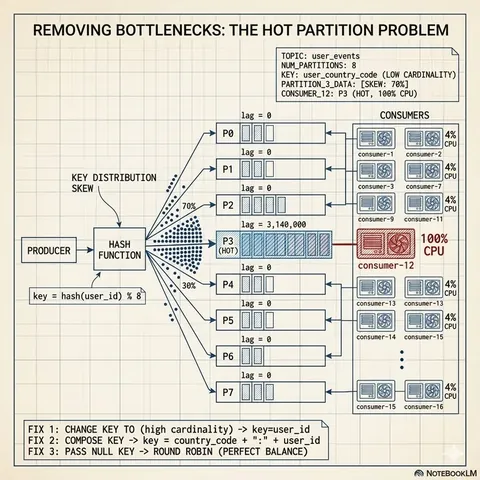
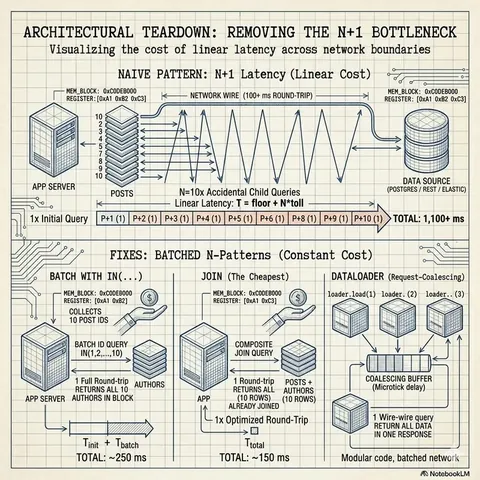
That's the third shape in Removing Bottlenecks: round-trip ceremony (N+1), worker-pool skew (hot partition), and control-plane data work (large file upload). The next one — request-path slow work — closes the family.
Knowledge Check
Why does the through-app upload pattern cause memory and disk pressure on your API server?