 insomnius

This is not a Kafka problem. It shows up under that name most often, but the same shape is in every system that hashes a key to pick a worker — sharded databases, DynamoDB partitions, Redis cluster slots, HDFS partition columns, consistent-hashing rings, even sticky-session load balancers. By the end you'll see it in all of them. The fix is structurally the same.
The producer dashboard says you're emitting 100,000 messages per second. The consumer dashboard says the fleet is processing 12,000. Lag is climbing by 88,000 messages every second and the on-call channel just lit up.
You scale the consumer group from 16 pods to 32. Nothing changes. You scale to 64. Still 12,000 a second. The CPU on most of the pods is at 4 %, but three of them are pegged at 100 %.
There's only one place this shape comes from. Open the consumer-group lag breakdown and look at the per-partition column:
partition  lag         consumer
P0         0           consumer-7
P1         0           consumer-3
P2         12          consumer-1
P3         3,140,000   consumer-12   ← here
P4         0           consumer-15
P5         18          consumer-9
P6         0           consumer-2
P7         0           consumer-5
One partition is carrying almost all the traffic. The other seven are idle. Adding consumers can't help — Kafka guarantees that within a consumer group, at most one consumer reads from each partition. You already have one consumer for P3; the other 63 pods are sitting next to it with nothing to do. The bottleneck isn't your fleet size. It's your partition key.
Watch the keys flow
The producer hashes whatever you pass as the key, then assigns the message to partition = hash(key) % numPartitions. If the key has high cardinality (millions of distinct values), the hash distributes evenly. If the key has low cardinality (eight country codes, three plan tiers, a handful of merchant categories), the hash can't distribute evenly — by pigeon-hole, most events land on a small number of partitions.
Toggle the keys below to feel the difference. Both modes ship 80 events at the same rate; only the key changes.
Partition key is country_code. 70 % of your traffic comes from one country, so 70 % of events hash into one partition.
The "low-cardinality" mode uses country_code with a realistic 70 % concentration in one country. The "high-cardinality" mode uses user_id. Same Kafka, same producer, same number of partitions, same number of consumers — and one of them ships fine, the other catches fire.
Why one consumer can't be many
The reason this isn't fixable from the consumer side is the ordering contract. Kafka guarantees per-partition order: events with the same key always land in the same partition, and within a partition, consumers see them in the order produced. That's the entire reason you'd choose a key in the first place — it's how user-42's "balance topup" event reliably arrives before the "purchase" event.
To honour that, the consumer group balancer hands each partition to exactly one consumer. Fanning out a hot partition across many workers would mean processing its events in parallel — which means out of order — which would break every downstream system that read the docs and trusted them.
So the rule is firm: a partition's throughput ceiling is whatever one consumer can do. And your partition's throughput floor is whatever your producer dumps onto it.
Same shape, different surface
Anywhere the system in front of you decides "which worker handles this thing?" by hashing some attribute of the request, the same skew lurks. A short tour:
- Sharded relational databases. A multi-tenant Postgres with
tenant_idas the shard key. Then your biggest customer signs on, lands on shard 4, and shard 4's CPU pegs while the other seven idle. The fix is the same: shard by something with finer cardinality, or compose(tenant_id, table_name)so hot tenants split across shards. - DynamoDB partition keys. AWS literally calls it the "hot partition" problem. Every Dynamo partition has a fixed throughput ceiling (3000 RCU / 1000 WCU). A skewed key concentrates traffic and you start getting
ProvisionedThroughputExceededExceptionon a table that's mostly idle. - Redis Cluster. 16384 hash slots split across N shards. Most keys spread fine, but a "celebrity" key — a single hot product page, a leaderboard for one game mode — pins one shard to 100 % CPU. Mitigations are key splitting (
leaderboard:{shard}) and read replicas. - HDFS / Hive / Parquet partitioning. When your table is partitioned by
event_dateand 90 % of analytical queries hit "today", today's partition is doing all the work. Subpartitioning by(event_date, hour)or(event_date, country)spreads the read load. - Consistent-hashing load balancers. Sticky sessions on
account_id. One whale account's session generates 80 % of one node's CPU. The fix is to either drop stickiness for the hot endpoints or hash on a finer attribute (request_idfor stateless paths). - gRPC / API rate-limiting buckets. Per-tenant token buckets with one tenant making 90 % of calls. The bucket's refill rate becomes everyone's effective rate.
The substrate changes — Kafka, Dynamo, Redis, HDFS — and the SDK changes — partitionKey, shard_key, hash_tag, partition_by. The diagnosis doesn't: a hash function turning a skewed input distribution into a skewed worker-load distribution. The fix is structurally the same — change what you hash on, until the input distribution is uniform enough.
Three ways to fix it
1. Pick a finer key
Often the simplest fix: replace a low-cardinality key with the natural high-cardinality identifier of the entity whose order you actually care about.
key=country_code   →   key=user_id
key=plan_tier      →   key=account_id
key=merchant_cat   →   key=merchant_id
This works because the real ordering requirement is almost always per-entity ("user-42's events in order"), not per-category ("all Indonesian events in order"). The category-level key was load-balancing accidentally, not by design.
2. Compose the key
When you do need locality at a category level — e.g. compliance rules require all Indonesian events to land in the same data centre — keep the category in the key but compose it with something high-cardinality:
key = country_code + ":" + user_id # "ID:42"Now ID:1, ID:2, ID:3 hash to different partitions, but user-42's ordering still holds because you always send their events with the same composite key. You preserve the ordering contract you actually need without the load skew.
3. Drop ordering when you don't need it
If you've audited the consumers and none of them depend on per-key order — say it's a fire-and-forget metrics topic, or a reindex stream where each event is an independent upsert — pass null as the key. Kafka's default partitioner will round-robin and you'll see perfect balance.
Surprisingly often the "we need ordering" requirement is folklore from a previous design. It costs nothing to ask the consumer team, and the answer is sometimes "no, idempotent upserts are fine."
A fourth fix exists for emergencies — internal worker pools per partition, where the consumer reads serially but dispatches to N goroutines / threads keyed by a sub-attribute. It buys throughput at the cost of strict ordering within the partition (you keep ordering between sub-keys but not between independent ones). Useful as a stopgap, dangerous as a default.
Three signals you have one
- Per-partition lag is asymmetric. Most partitions at 0, one or two carrying millions. Don't look at the topic-level lag average; look at the breakdown.
- Adding consumers doesn't help. If 16 → 64 pods produces zero throughput improvement, you're partition-bound, not consumer-bound.
- CPU per consumer is bimodal. A few pods at 100 %, the rest at single digits. The flat distribution is what healthy looks like; bimodal is what hot partition looks like.
Rule of Thumb
A partition key is a load balancer wearing different clothes. Its cardinality determines your max parallelism, and its distribution determines whether you'll actually achieve it. When a key has fewer distinct values than partitions, you've capped your throughput at one-Nth of theoretical and given that ceiling to whichever value happens to be the most popular.
Before picking any key — Kafka, Dynamo, Redis, shards, sessions — ask two questions. How many distinct values will this take in production? and What does the value distribution look like at the 99th percentile? If either answer worries you, you've found a hot partition before it found you.
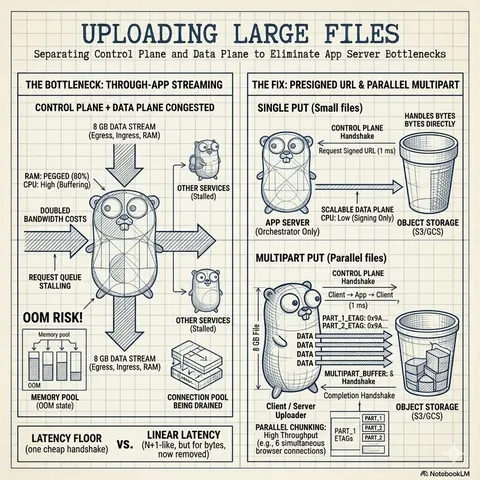
Next in Removing Bottlenecks: Uploading large files — why streaming 8 GB through your app server is the wrong shape, and how presigned URLs and multipart uploads let the client send straight to the bucket.
Knowledge Check
A Kafka consumer group has 64 pods. Three of them are pegged at 100% CPU; the rest sit at 4%. What's the most likely cause?